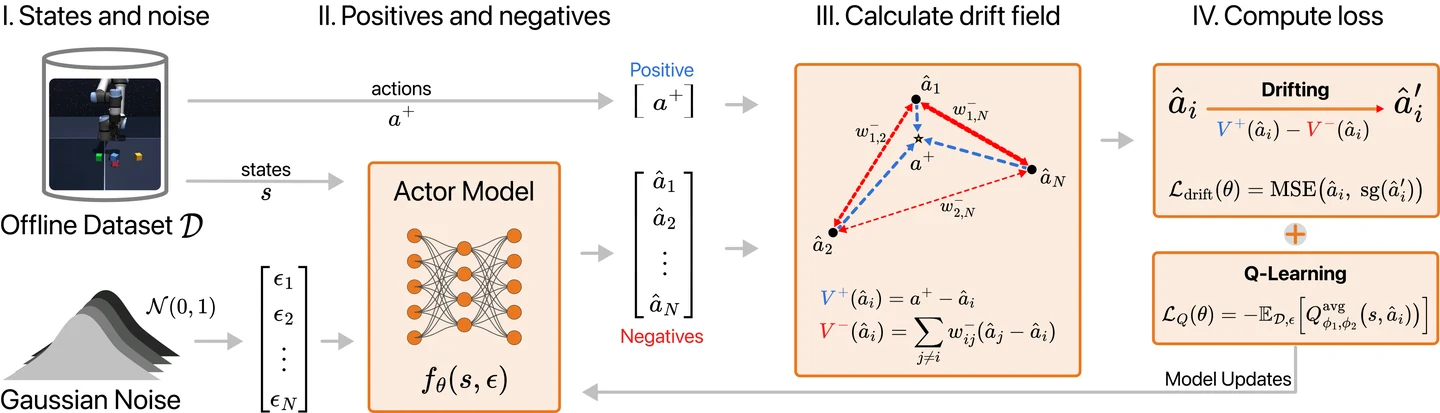
Attraction, repulsion, and critic signals shaping the DriftQL drift field.

Drift Q-Learning

DriftQL is a one-step offline RL policy that replaces diffusion and flow denoising with a learned drift field: attraction keeps actions on the data, repulsion keeps them diverse, and the critic tilts them toward high value. State of the art on D4RL and OGBench, and robust to noisy datasets.
May 2026 · Anas Houssaini
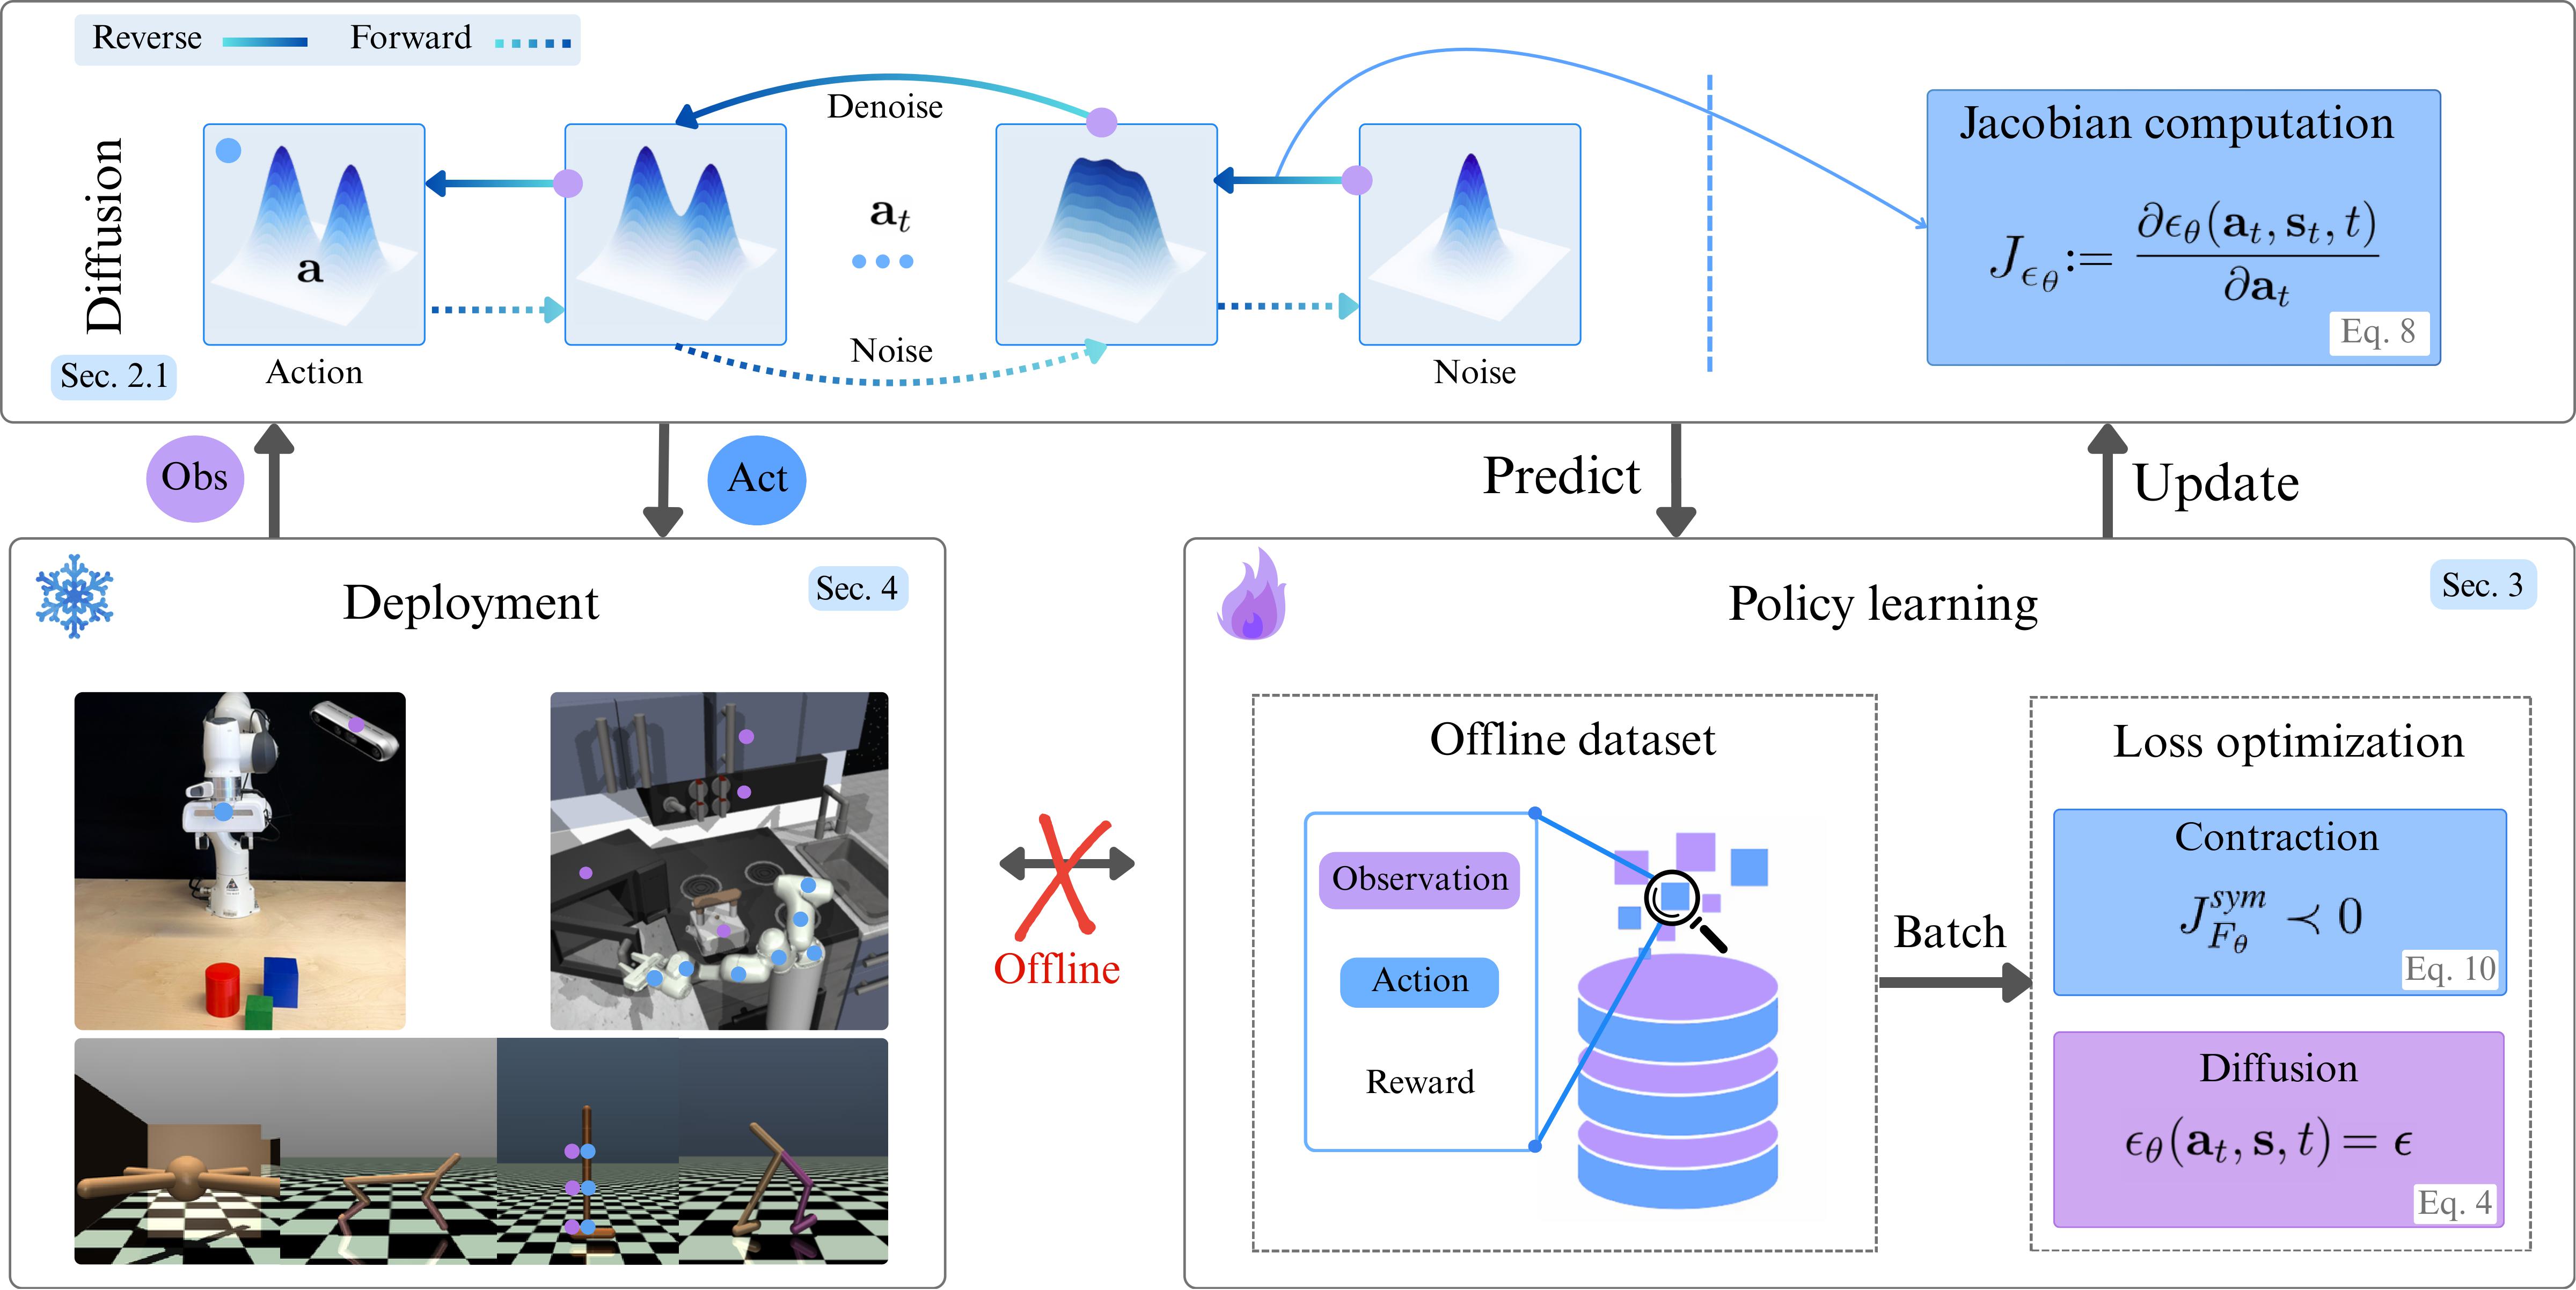
Methodology overview of Contractive Diffusion Policies.

Contractive Diffusion Policies: Robust Action Diffusion via Contractive Score-Based Sampling with Differential Equations

CDPs add a contraction regularizer to diffusion policies that pulls nearby sampling flows together, suppressing solver and score-matching errors and unwanted action variance. Backed by theory and a practical recipe with a single extra hyperparameter, they often outperform standard diffusion policies in simulation and on real robots, most clearly when data is scarce.

January 2026 · Anas Houssaini